
11.4: One-Way ANOVA
- Page ID
- 11018

\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\( \newcommand{\dsum}{\displaystyle\sum\limits} \)
\( \newcommand{\dint}{\displaystyle\int\limits} \)
\( \newcommand{\dlim}{\displaystyle\lim\limits} \)
\( \newcommand{\id}{\mathrm{id}}\) \( \newcommand{\Span}{\mathrm{span}}\)
( \newcommand{\kernel}{\mathrm{null}\,}\) \( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\) \( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\) \( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\id}{\mathrm{id}}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\kernel}{\mathrm{null}\,}\)
\( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\)
\( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\)
\( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\) \( \newcommand{\AA}{\unicode[.8,0]{x212B}}\)
\( \newcommand{\vectorA}[1]{\vec{#1}} % arrow\)
\( \newcommand{\vectorAt}[1]{\vec{\text{#1}}} % arrow\)
\( \newcommand{\vectorB}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vectorC}[1]{\textbf{#1}} \)
\( \newcommand{\vectorD}[1]{\overrightarrow{#1}} \)
\( \newcommand{\vectorDt}[1]{\overrightarrow{\text{#1}}} \)
\( \newcommand{\vectE}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash{\mathbf {#1}}}} \)
\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\(\newcommand{\longvect}{\overrightarrow}\)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\(\newcommand{\avec}{\mathbf a}\) \(\newcommand{\bvec}{\mathbf b}\) \(\newcommand{\cvec}{\mathbf c}\) \(\newcommand{\dvec}{\mathbf d}\) \(\newcommand{\dtil}{\widetilde{\mathbf d}}\) \(\newcommand{\evec}{\mathbf e}\) \(\newcommand{\fvec}{\mathbf f}\) \(\newcommand{\nvec}{\mathbf n}\) \(\newcommand{\pvec}{\mathbf p}\) \(\newcommand{\qvec}{\mathbf q}\) \(\newcommand{\svec}{\mathbf s}\) \(\newcommand{\tvec}{\mathbf t}\) \(\newcommand{\uvec}{\mathbf u}\) \(\newcommand{\vvec}{\mathbf v}\) \(\newcommand{\wvec}{\mathbf w}\) \(\newcommand{\xvec}{\mathbf x}\) \(\newcommand{\yvec}{\mathbf y}\) \(\newcommand{\zvec}{\mathbf z}\) \(\newcommand{\rvec}{\mathbf r}\) \(\newcommand{\mvec}{\mathbf m}\) \(\newcommand{\zerovec}{\mathbf 0}\) \(\newcommand{\onevec}{\mathbf 1}\) \(\newcommand{\real}{\mathbb R}\) \(\newcommand{\twovec}[2]{\left[\begin{array}{r}#1 \\ #2 \end{array}\right]}\) \(\newcommand{\ctwovec}[2]{\left[\begin{array}{c}#1 \\ #2 \end{array}\right]}\) \(\newcommand{\threevec}[3]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \end{array}\right]}\) \(\newcommand{\cthreevec}[3]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \end{array}\right]}\) \(\newcommand{\fourvec}[4]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \\ #4 \end{array}\right]}\) \(\newcommand{\cfourvec}[4]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \\ #4 \end{array}\right]}\) \(\newcommand{\fivevec}[5]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \\ #4 \\ #5 \\ \end{array}\right]}\) \(\newcommand{\cfivevec}[5]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \\ #4 \\ #5 \\ \end{array}\right]}\) \(\newcommand{\mattwo}[4]{\left[\begin{array}{rr}#1 \amp #2 \\ #3 \amp #4 \\ \end{array}\right]}\) \(\newcommand{\laspan}[1]{\text{Span}\{#1\}}\) \(\newcommand{\bcal}{\cal B}\) \(\newcommand{\ccal}{\cal C}\) \(\newcommand{\scal}{\cal S}\) \(\newcommand{\wcal}{\cal W}\) \(\newcommand{\ecal}{\cal E}\) \(\newcommand{\coords}[2]{\left\{#1\right\}_{#2}}\) \(\newcommand{\gray}[1]{\color{gray}{#1}}\) \(\newcommand{\lgray}[1]{\color{lightgray}{#1}}\) \(\newcommand{\rank}{\operatorname{rank}}\) \(\newcommand{\row}{\text{Row}}\) \(\newcommand{\col}{\text{Col}}\) \(\renewcommand{\row}{\text{Row}}\) \(\newcommand{\nul}{\text{Nul}}\) \(\newcommand{\var}{\text{Var}}\) \(\newcommand{\corr}{\text{corr}}\) \(\newcommand{\len}[1]{\left|#1\right|}\) \(\newcommand{\bbar}{\overline{\bvec}}\) \(\newcommand{\bhat}{\widehat{\bvec}}\) \(\newcommand{\bperp}{\bvec^\perp}\) \(\newcommand{\xhat}{\widehat{\xvec}}\) \(\newcommand{\vhat}{\widehat{\vvec}}\) \(\newcommand{\uhat}{\widehat{\uvec}}\) \(\newcommand{\what}{\widehat{\wvec}}\) \(\newcommand{\Sighat}{\widehat{\Sigma}}\) \(\newcommand{\lt}{<}\) \(\newcommand{\gt}{>}\) \(\newcommand{\amp}{&}\) \(\definecolor{fillinmathshade}{gray}{0.9}\)Introduction
Many statistical applications in psychology, social science, business administration, and the natural sciences involve several groups. For example, an environmentalist is interested in knowing if the average amount of pollution varies in several bodies of water. A sociologist is interested in knowing if the amount of income a person earns varies according to his or her upbringing. A consumer looking for a new car might compare the average gas mileage of several models.
For hypothesis tests comparing averages between more than two groups, statisticians have developed a method called "Analysis of Variance" (abbreviated ANOVA). In this chapter, you will study the simplest form of ANOVA called single factor or one-way ANOVA. You will also study the \(F\) distribution, used for one-way ANOVA, and the test of two variances. This is just a very brief overview of one-way ANOVA. You will study this topic in much greater detail in future statistics courses. One-Way ANOVA, as it is presented here, relies heavily on a calculator or computer.
The purpose of a one-way ANOVA test is to determine the existence of a statistically significant difference among several group means. The test actually uses variances to help determine if the means are equal or not. Since the number of groups we are comparing, along with the number of values in each group, plays into the degrees of freedom, the tables for the F-distribution are many. For that reason, we will not use the Critical Values (traditional method) for determining significance. The calculation for the test statistic is also a rather length process. For the most part, when conducting a significance test for the difference among several group means (ANOVA) we will use a calculator or computer function to identify the test statistic and the p-value, much like we did with the chi-squared test for independence. However, since the values that are necessary for the test statistics calculation also convey some interesting information, we will review those values and the full calculation process as well.
Facts about the \(F\) distribution:
- The curve is not symmetrical but skewed to the right.
- There is a different curve for each set of \(dfs\).
- The \(F\) statistic is greater than or equal to zero.
- As the degrees of freedom for the numerator and for the denominator get larger, the curve approximates the normal.
- Other uses for the \(F\) distribution include comparing two variances and two-way Analysis of Variance. Two-Way Analysis is beyond the scope of this course.
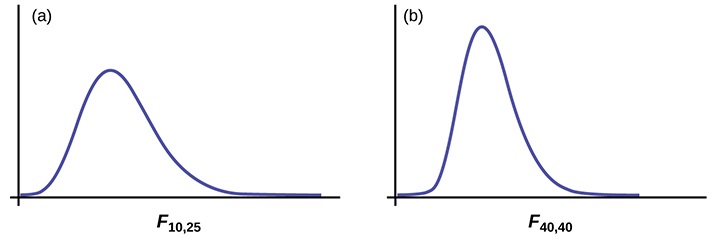
We will do a deeper dive into the F-distribution and how those values are calculated later on in this section.
Significance Testing
We will follow the same five steps as earlier chapters:
- Setup the Hypotheses
- Find the test statistic
- Find the Critical Value or the p-value
- Note: Even though the tables for the F Distribution exist, we will focus on the technology use and p-value method in these examples.
- Make a Decision about \(H_0\)
- State the Conclusion.
To perform a one-way ANOVA test, there are several basic assumptions to be fulfilled:
- Each population from which a sample is taken is assumed to be normal.
- All samples are randomly selected and independent.
- The populations are assumed to have equal standard deviations (or variances).
- The factor is a categorical variable.
- The response is a numerical variable.
The Null and Alternative Hypotheses
The null hypothesis is simply that all the group population means are the same. The alternative hypothesis is that at least one pair of means is different. For example, if there are \(k\) groups:
- \(H_{0}: \mu_{1} = \mu_{2} = \mu_{3} = \dotsc = \mu_{k}\)
- \(H_{a}: \text{At least two of the group means} \mu_{2} = \mu_{3} = \dotsc = \mu_{k} \text{are not equal}\)
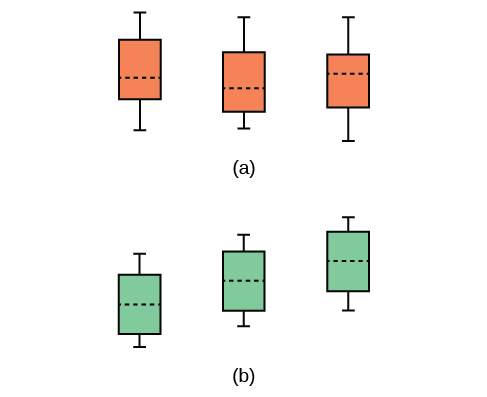
The graphs, a set of box plots representing the distribution of values with the group means indicated by a horizontal line through the box, help in the understanding of the hypothesis test. In the first graph (red box plots), \(H_{0}: \mu_{1} = \mu_{2} = \mu_{3}\) and the three populations have the same distribution if the null hypothesis is true. The variance of the combined data is approximately the same as the variance of each of the populations.
If the null hypothesis is false, then the variance of the combined data is larger which is caused by the different means as shown in the second graph (green box plots).
Test statistic and P-value
We will go more in-dept into the calculation of the test statistic momentarily, but for now, we will look at the useful calculator functions for these tests:
To calculate the F test statistic,
- Press
STATandEdit - Enter the data into lists L1, L2, L3, ... Lk, where \(k\) is number of groups you are comparing.
- These lists do not all need to be the same length.
- Press
STATand arrow over toTESTS. - Arrow down to
ANOVA. PressENTER. - Enter (
L1,L2,L3,...,Lk). Press Enter.
The results screen looks like:


The \(F\) value is the test statistic, followed by the \(p\)-value. The Factor and Error information will be reviewed a little later when we look at the calculations that go into finding the test statistics.
If you do calculate the test statistic "by hand," then you may need to calculate the p-value, you can use the Fcdf() function in your list of distributions on your TI 83/84 calculator. To use this function, you need to know the Lower Bound, Upper Bound, Degrees of Freedom of the Numerator (dfNumer) and the Degrees of Freedom of the Denominator (dfDenom).
The \(dfs\) for the numerator \(= \text{the number of groups} - 1 = k - 1\).
- \(k\) is the number of groups.
- In the screenshot above, this is the df under Factor.
The \(dfs\) for the denominator \(= \text{the total number of samples} - \text{the number of groups} = N - k\)
- N is the total number of data values. In otherwords, find the number of data values in each group and add them all together.
- In the screenshot above, this is the df under Error.
If you are only comparing the means from two populations, then ANOVA is not necessary. Instead, you will use a T test for independent populations.
As part of an experiment to see how different types of soil cover would affect slicing tomato production, Marist College students grew tomato plants under different soil cover conditions. Groups of three plants each had one of the following treatments
straw
- bare soil
- a commercial ground cover
- black plastic
- compost
All plants grew under the same conditions and were the same variety. Students recorded the weight (in grams) of tomatoes produced by each of the \(n = 15\) plants:
| Bare: \(n_{1} = 3\) | Ground Cover: \(n_{2} = 3\) | Plastic: \(n_{3} = 3\) | Straw: \(n_{4} = 3\) | Compost: \(n_{5} = 3\) |
|---|---|---|---|---|
| 2,625 | 5,348 | 6,583 | 7,285 | 6,277 |
| 2,997 | 5,682 | 8,560 | 6,897 | 7,818 |
| 4,915 | 5,482 | 3,830 | 9,230 | 8,677 |
The tomato yields under the five mulching conditions are represented by \(\mu_{1}, \mu_{2}, \mu_{3}, \mu_{4}, \mu_{5}\). We will conduct a hypothesis test to determine if all means are the same or at least one is different. Using a significance level of 5%, test the null hypothesis that there is no difference in mean yields among the five groups against the alternative hypothesis that at least one mean is different from the rest.
Solutions
Step 1:
The null and alternative hypotheses are:
- \(H_{0}: \mu_{1} = \mu_{2} = \mu_{3} = \mu_{4} = \mu_{5}\) (Claim)
- \(H_{1}: \mu_{i} \neq \mu_{j}\) some \(i \neq j\)
Step 2: Use the ANOVA TEST
Test statistic: \(F = 4.4810\)
Step 3:
Distribution for the test: \(F_{4,10}\)
\(df(\text{num}) = 5 - 1 = 4\)
\(df(\text{denom}) = 15 - 5 = 10\)
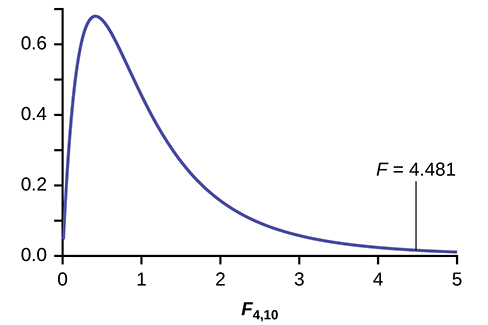
\(p\text{-value} = Fcdf(4.481, 999, 4, 10) = 0.0248\). Or use the value from the ANOVA Test.
Step 4:
Compare \(\alpha\) and the \(p\text{-value}\): \(\alpha = 0.05, p\text{-value} = 0.0248\)
\(0.0248 \leq 0.05\) so reject \(H_0\).
Step 5:
Conclusion: At the 5% significance level, we have reasonably strong evidence to reject the claim that the mean yields for slicing tomato plants grown under different mulching conditions are the same, and unlikely to be due to chance alone. We may conclude that at least some of mulches led to different mean yields.
MRSA, or Staphylococcus aureus, can cause a serious bacterial infections in hospital patients. Table shows various colony counts from different patients who may or may not have MRSA.
| Conc = 0.6 | Conc = 0.8 | Conc = 1.0 | Conc = 1.2 | Conc = 1.4 |
|---|---|---|---|---|
| 9 | 16 | 22 | 30 | 27 |
| 66 | 93 | 147 | 199 | 168 |
| 98 | 82 | 120 | 148 | 132 |
Test whether the mean number of colonies are the same or are different. State the null and alternate hypotheses, find the p-value, and state your conclusion. Use a 5% significance level.
- Answer
-
We test for the equality of mean number of colonies:
\(H_{0}: \mu_{1} = \mu_{2} = \mu_{3} = \mu_{4} = \mu_{5}\)
\(H_{1}: \mu_{i} \neq \mu_{j}\) some \(i \neq j\)
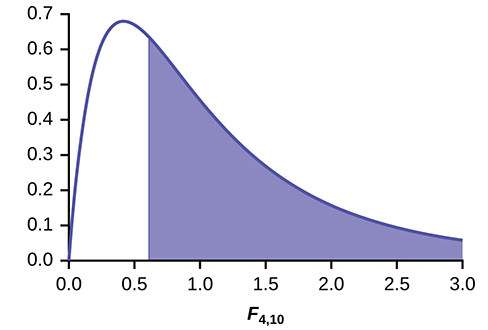
Figure \(\PageIndex{5}\)
Distribution for the test: \(F_{4,10}\)
\(p\text{-value} = 0.6649\).
Compare \(\alpha\) and the \(p\text{-value}\): \(\alpha = 0.05, p\text{-value} = 0.669\)
Make a decision: Since \(p\text{-value} > \alpha \), we do not reject \(H_{0}\).
Conclusion: At the 5% significance level, there is insufficient evidence from these data that different levels of tryptone will cause a significant difference in the mean number of bacterial colonies formed.
Four sororities took a random sample of sisters regarding their grade means for the past term. The results are shown in Table.
| Sorority 1 | Sorority 2 | Sorority 3 | Sorority 4 |
|---|---|---|---|
| 2.17 | 2.63 | 2.63 | 3.79 |
| 1.85 | 1.77 | 3.78 | 3.45 |
| 2.83 | 3.25 | 4.00 | 3.08 |
| 1.69 | 1.86 | 2.55 | 2.26 |
| 3.33 | 2.21 | 2.45 | 3.18 |
Using a significance level of 1%, is there a difference in mean grades among the sororities?
Solution
Step 1:
Let \(\mu_{1}, \mu_{2}, \mu_{3}, \mu_{4}\) be the population means of the sororities. Remember that the null hypothesis claims that the sorority groups are from the same normal distribution. The alternate hypothesis says that at least two of the sorority groups come from populations with different normal distributions. Notice that the four sample sizes are each five.
This is an example of a balanced design, because each factor (i.e., sorority) has the same number of observations.
\(H_{0}: \mu_{1} = \mu_{2} = \mu_{3} = \mu_{4}\)
\(H_{1}\): Not all of the means \(\mu_{1}, \mu_{2}, \mu_{3}, \mu_{4}\) are equal.
Step 2:
Calculate the test statistic: \(F = 2.23\)
Step 3:
Distribution for the test: \(F_{3,16}\)
where \(k = 4\) groups and \(n = 20\) samples in total
\(df(\text{num}) = k - 1 = 4 - 1 = 3\)
\(df(\text{denom}) = n - k = 20 - 4 = 16\)
Graph:
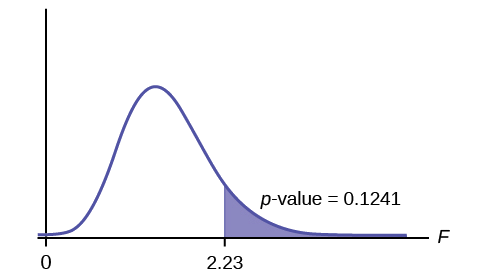
\(p\text{-value} = Fcdf(2.23,999,3,16) = 0.1241\)
Step 4:
Compare \(\alpha\) and the \(p\text{-value}\): \(\alpha = 0.01\)
\(0.1241 > 0.01\) So, you cannot reject \(H_{0}\).
Step 5:
Conclusion: Using a significance level of 1%, there is not sufficient evidence to conclude that there is a difference among the mean grades for the sororities.
Four sports teams took a random sample of players regarding their GPAs for the last year. The results are shown in Table.
| Basketball | Baseball | Hockey | Lacrosse |
|---|---|---|---|
| 3.6 | 2.1 | 4.0 | 2.0 |
| 2.9 | 2.6 | 2.0 | 3.6 |
| 2.5 | 3.9 | 2.6 | 3.9 |
| 3.3 | 3.1 | 3.2 | 2.7 |
| 3.8 | 3.4 | 3.2 | 2.5 |
Use a significance level of 5%, and determine if there is a difference in GPA among the teams.
- Answer
-
With a \(p\text{-value}\) of \(0.9271\), we do not reject the null hypothesis. Using a significance level of 5%, there is not sufficient evidence to conclude that there is a difference among the GPAs for the sports teams.
Steps for Calculating the F Test Statistic
The distribution used for the hypothesis test is a new one. It is called the \(F\) distribution, named after Sir Ronald Fisher, an English statistician. The \(F\) statistic is a ratio (a fraction). There are two sets of degrees of freedom; one for the numerator and one for the denominator.
For example, if \(F\) follows an \(F\) distribution and the number of degrees of freedom for the numerator is four, and the number of degrees of freedom for the denominator is ten, then \(F \sim F_{4,10}\).
The \(F\) distribution is derived from the Student's \(t\)-distribution. The values of the \(F\) distribution are squares of the corresponding values of the \(t\)-distribution. One-Way ANOVA expands the \(t\)-test for comparing more than two groups. The scope of that derivation is beyond the level of this course.
To calculate the \(F\) ratio, two estimates of the variance are made.
- Variance between samples: An estimate of \(\sigma^{2}\) that is the variance of the sample means multiplied by \(n\) (when the sample sizes are the same.). If the samples are different sizes, the variance between samples is weighted to account for the different sample sizes. The variance is also called variation due to treatment or explained variation.
- Variance within samples: An estimate of \(\sigma^{2}\) that is the average of the sample variances (also known as a pooled variance). When the sample sizes are different, the variance within samples is weighted. The variance is also called the variation due to error or unexplained variation.
- \(SS_{\text{between}} = \text{the sum of squares that represents the variation among the different samples}\)
- \(SS_{\text{within}} = \text{the sum of squares that represents the variation within samples that is due to chance}\).
To find a "sum of squares" means to add together squared quantities that, in some cases, may be weighted. We used sum of squares to calculate the sample variance and the sample standard deviation in discussed previously.
\(MS\) means "mean square." \(MS_{\text{between}}\) is the variance between groups, and \(MS_{\text{within}}\) is the variance within groups.
- \(k =\) the number of different groups
- \(n_{j} =\) the size of the \(j^{th}\) group}
- \(s_{j} =\) the sum of the values in the \(j^{th}\) group
- \(n =\) total number of all the values combined (total sample size): \[n= \sum n_{j}\]
- \(x =\) one value: \[\sum x = \sum s_{j}\]
- Sum of squares of all values from every group combined: \[\sum x^{2}\]
- Between group variability: \[SS_{\text{total}} = \sum x^{2} - \dfrac{\left(\sum x^{2}\right)}{n}\]
- Total sum of squares: \[\sum x^{2} - \dfrac{\left(\sum x\right)^{2}}{n}\]
- Explained variation: sum of squares representing variation among the different samples: \[SS_{\text{between}} = \sum \left[\dfrac{(s_{j})^{2}}{n_{j}}\right] - \dfrac{\left(\sum s_{j}\right)^{2}}{n}\]
- Unexplained variation: sum of squares representing variation within samples due to chance: \[SS_{\text{within}} = SS_{\text{total}} - SS_{\text{between}}\]
- \(df\)'s for different groups (\(df\)'s for the numerator): \[df = k - 1\]
- Equation for errors within samples (\(df\)'s for the denominator): \[df_{\text{within}} = n - k\]
- Mean square (variance estimate) explained by the different groups: \[MS_{\text{between}} = \dfrac{SS_{\text{between}}}{df_{\text{between}}}\]
- Mean square (variance estimate) that is due to chance (unexplained): \[MS_{\text{within}} = \dfrac{SS_{\text{within}}}{df_{\text{within}}}\]
\(MS_{\text{between}}\) and \(MS_{\text{within}}\) can be written as follows:
\[MS_{\text{between}} = \dfrac{SS_{\text{between}}}{df_{\text{between}}} = \dfrac{SS_{\text{between}}}{k - 1}\]
\[MS_{\text{within}} = \dfrac{SS_{\text{within}}}{df_{\text{within}}} = \dfrac{SS_{\text{within}}}{n - k}\]
The one-way ANOVA test depends on the fact that \(MS_{\text{between}}\) can be influenced by population differences among means of the several groups. Since \(MS_{\text{within}}\) compares values of each group to its own group mean, the fact that group means might be different does not affect \(MS_{\text{within}}\).
The null hypothesis says that all groups are samples from populations having the same normal distribution. The alternate hypothesis says that at least two of the sample groups come from populations with different normal distributions. If the null hypothesis is true, \(MS_{\text{between}}\) and \(MS_{\text{within}}\) should both estimate the same value.
The null hypothesis says that all the group population means are equal. The hypothesis of equal means implies that the populations have the same normal distribution, because it is assumed that the populations are normal and that they have equal variances.
\(F\)-Ratio or \(F\) Statistic
\[F = \dfrac{MS_{\text{between}}}{MS_{\text{within}}}\]
If \(MS_{\text{between}}\) and \(MS_{\text{within}}\) estimate the same value (following the belief that \(H_{0}\) is true), then the \(F\)-ratio should be approximately equal to one. Mostly, just sampling errors would contribute to variations away from one. As it turns out, \(MS_{\text{between}}\) consists of the population variance plus a variance produced from the differences between the samples. \(MS_{\text{within}}\) is an estimate of the population variance. Since variances are always positive, if the null hypothesis is false, \(MS_{\text{between}}\) will generally be larger than \(MS_{\text{within}}\).Then the \(F\)-ratio will be larger than one. However, if the population effect is small, it is not unlikely that \(MS_{\text{within}}\) will be larger in a given sample.
The foregoing calculations were done with groups of different sizes. If the groups are the same size, the calculations simplify somewhat and the \(F\)-ratio can be written as:
\[F = \dfrac{n \cdot s_{\bar{x}}^{2}}{s^{2}_{\text{pooled}}}\]
where ...
- \(n = \text{the sample size}\)
- \(df_{\text{numerator}} = k - 1\)
- \(df_{\text{denominator}} = n - k\)
- \(s^{2}_{\text{pooled}} = \text{the mean of the sample variances (pooled variance)}\)
- \(s_{\bar{x}^{2}} = \text{the variance of the sample means}\)
Data are typically put into a table for easy viewing. One-Way ANOVA results are often displayed in this manner by computer software. This is the same information displayed in the TI 84 results screens from Figure \(\PageIndex{3}\).
| Source of Variation | Sum of Squares (\(SS\)) | Degrees of Freedom (\(df\)) | Mean Square (\(MS\)) | \(F\) |
|---|---|---|---|---|
|
Factor (Between) |
\(SS(\text{Factor})\) | \(k - 1\) | \(MS(\text{Factor}) = \dfrac{SS(\text{Factor})}{(k - 1)}\) | \(F = \dfrac{MS(\text{Factor})}{MS(\text{Error})}\) |
|
Error (Within) |
\(SS(\text{Error})\) | \(n - k\) | \(MS(\text{Error}) = \dfrac{SS(\text{Error})}{(n - k)}\) | |
| Total | \(SS(\text{Total})\) | \(n - 1\) |
Three different diet plans are to be tested for mean weight loss. The entries in the table are the weight losses for the different plans. The one-way ANOVA results are shown in Table.
| Plan 1: \(n_{1} = 4\) | Plan 2: \(n_{2} = 3\) | Plan 3: \(n_{3} = 3\) |
|---|---|---|
| 5 | 3.5 | 8 |
| 4.5 | 7 | 4 |
| 4 | 3.5 | |
| 3 | 4.5 |
\[s_{1} = 16.5, s_{2} =15, s_{3} = 15.7 \nonumber\]
Following are the calculations needed to fill in the one-way ANOVA table. The table is used to conduct a hypothesis test.
\[\begin{align} SS(\text{between}) &= \sum \left[\dfrac{(s_{j})^{2}}{n_{j}}\right] - \dfrac{\left(\sum s_{j}\right)^{2}}{n} \nonumber \\ &= \dfrac{s^{2}_{1}}{4} + \dfrac{s^{2}_{2}}{3} + \dfrac{s^{2}_{3}}{3} + \dfrac{(s_{1} + s_{2} + s_{3})^{2}}{10} \nonumber \end{align}\]
where \(n_{1} = 4, n_{2} = 3, n_{3} = 3\) and \(n = n_{1} + n_{2} + n_{3} = 10\) so
\[\begin{align} SS(\text{between}) &= \dfrac{(16.5)^{2}}{4} + \dfrac{(15)^{2}}{3} + \dfrac{(5.5)^{2}}{3} = \dfrac{(16.5 + 15 + 15.5)^{2}}{10} \nonumber \\ &= 2.2458 \nonumber \end{align}\]
\[\begin{align} S(\text{total}) =& \sum x^{2} - \dfrac{\left(\sum x\right)^{2}}{n} \nonumber\\ =& (5^{2} + 4.5^{2} + 4^{2} + 3^{2} + 3.5^{2} + 7^{2} + 4.5^{2} + 8^{2} + 4^{2} + 3.5^{2}) \nonumber\\ &− \dfrac{(5 + 4.5 + 4 + 3 + 3.5 + 7 + 4.5 + 8 + 4 + 3.5)^{2}}{10} \nonumber\\ =& 244 - \dfrac{47^{2}}{10} = 244 - 220.9 \nonumber\\ =& 23.1 \nonumber\end{align}\]
\[\begin{align} SS(\text{within}) &= SS(\text{total}) - SS(\text{between}) \nonumber\\ &= 23.1 - 2.2458 \nonumber\\ &= 20.8542 \nonumber\end{align}\]
One-Way ANOVA Table: The formulas for \(SS(\text{Total})\), \(SS(\text{Factor}) = SS(\text{Between})\) and \(SS(\text{Error}) = SS(\text{Within})\) as shown previously. The same information is provided by the TI calculator hypothesis test function ANOVA in STAT TESTS (syntax is \(ANOVA(L1, L2, L3)\) where \(L1, L2, L3\) have the data from Plan 1, Plan 2, Plan 3 respectively).
| Source of Variation | Sum of Squares (\(SS\)) | Degrees of Freedom (\(df\)) | Mean Square (\(MS\)) | \(F\) |
|---|---|---|---|---|
| Factor (Between) |
\(SS(\text{Factor}) = SS(\text{Between}) = 2.2458\) | \(k - 1= 3 \text{ groups} - 1 = 2\) | \(MS(\text{Factor}) = \dfrac{SS(\text{Factor})}{(k– 1)} = \dfrac{2.2458}{2} = 1.1229\) | \(F = \dfrac{MS(\text{Factor})}{MS(\text{Error})} = \dfrac{1.1229}{2.9792} = 0.3769\) |
| Error (Within) |
\(SS(\text{Error}) = SS(\text{Within}) = 20.8542\) | \(n – k = 10 \text{ total data} - 3 \text{ groups} = 7\) | \(MS(\text{Error})) = \dfrac{SS(\text{Error})}{(n– k)} = \dfrac{20.8542}{7} = 2.9792\) | |
| Total | \(SS(\text{Total}) = 2.2458 + 20.8542 = 23.1\) | \(n - 1 = 10 \text{ total data} - 1 = 9\) |
As part of an experiment to see how different types of soil cover would affect slicing tomato production, Marist College students grew tomato plants under different soil cover conditions. Groups of three plants each had one of the following treatments
- bare soil
- a commercial ground cover
- black plastic
- straw
- compost
All plants grew under the same conditions and were the same variety. Students recorded the weight (in grams) of tomatoes produced by each of the \(n = 15\) plants:
| Bare: \(n_{1} = 3\) | Ground Cover: \(n_{2} = 3\) | Plastic: \(n_{3} = 3\) | Straw: \(n_{4} = 3\) | Compost: \(n_{5} = 3\) |
|---|---|---|---|---|
| 2,625 | 5,348 | 6,583 | 7,285 | 6,277 |
| 2,997 | 5,682 | 8,560 | 6,897 | 7,818 |
| 4,915 | 5,482 | 3,830 | 9,230 | 8,677 |
Create the one-way ANOVA table.
- Answer
-
One-Way ANOVA table Source of Variation Sum of Squares (\(SS\)) Degrees of Freedom (\(df\)) Mean Square (\(MS\)) \(F\) Factor (Between) 36,648,561 \(5 - 1 = 4\) \(\dfrac{36,648,561}{4} = 9,162,140\) \(\dfrac{9,162,140}{2,044,672.6} = 4.4810\) Error (Within) 20,446,726 \(15 - 5 = 10\) \(\dfrac{20,446,726}{10} = 2,044,672.6\) Total 57,095,287 \(15 - 1 = 14\)
The one-way ANOVA hypothesis test is always right-tailed because larger \(F\)-values are way out in the right tail of the \(F\)-distribution curve and tend to make us reject \(H_{0}\).
A fourth grade class is studying the environment. One of the assignments is to grow bean plants in different soils. Tommy chose to grow his bean plants in soil found outside his classroom mixed with dryer lint. Tara chose to grow her bean plants in potting soil bought at the local nursery. Nick chose to grow his bean plants in soil from his mother's garden. No chemicals were used on the plants, only water. They were grown inside the classroom next to a large window. Each child grew five plants. At the end of the growing period, each plant was measured, producing the data (in inches) in Table \(\PageIndex{3}\).
| Tommy's Plants | Tara's Plants | Nick's Plants |
|---|---|---|
| 24 | 25 | 23 |
| 21 | 31 | 27 |
| 23 | 23 | 22 |
| 30 | 20 | 30 |
| 23 | 28 | 20 |
Does it appear that the three media in which the bean plants were grown produce the same mean height? Test at a 3% level of significance.
Solution
Step 1:
\(H_{0}: \mu_{1} = \mu_{2} = \mu_{3} \) (Claim)
\(H_{1}\): Not all of the means \(\mu_{1}, \mu_{2}, \mu_{3}) are equal.
Step 2:
This time, we will perform the calculations that lead to the \(F'\) statistic. Notice that each group has the same number of plants, so we will use the formula
\[F' = \dfrac{n \cdot s_{\bar{x}}^{2}}{s^{2}_{\text{pooled}}}.\]
First, calculate the sample mean and sample variance of each group.
| Tommy's Plants | Tara's Plants | Nick's Plants | |
|---|---|---|---|
| Sample Mean | 24.2 | 25.4 | 24.4 |
| Sample Variance | 11.7 | 18.3 | 16.3 |
Next, calculate the variance of the three group means (Calculate the variance of 24.2, 25.4, and 24.4). Variance of the group means \(= 0.413 = s_{\bar{x}}^{2}\)
Then \(MS_{\text{between}} = ns_{\bar{x}}^{2} = (5)(0.413)\) where \(n = 5\) is the sample size (number of plants each child grew).
Calculate the mean of the three sample variances (Calculate the mean of 11.7, 18.3, and 16.3). Mean of the sample variances \(= 15.433 = s^{2}_{\text{pooled}}\)
Then \(MS_{\text{within}} = s^{2}_{\text{pooled}} = 15.433\).
The \(F\) statistic (or \(F\) ratio) is \(F = \dfrac{MS_{\text{between}}}{MS_{\text{within}}} = \dfrac{ns_{\bar{x}}^{2}}{s^{2}_{\text{pooled}}} = \dfrac{(5)(0.413)}{15.433} = 0.134\)
The \(dfs\) for the numerator \(= \text{the number of groups} - 1 = 3 - 1 = 2\).
The \(dfs\) for the denominator \(= \text{the total number of samples} - \text{the number of groups} = 15 - 3 = 12\)
The distribution for the test is \(F_{2,12}\) and the \(F\) statistic is \(F = 0.134\)
Step 3:
The \(p\text{-value} = Fcdf(0.134,999,2,12) = 0.8759\).
Step 4:
\(\alpha = 0.03\) and the \(p\text{-value} = 0.8759\)
\(0.8759 >0.03\) So, do not reject \(H_{0}\).
Step 5:
Conclusion: With a 3% level of significance, from the sample data, the evidence is not sufficient to reject that the mean heights of the bean plants are the same.
Another fourth grader also grew bean plants, but this time in a jelly-like mass. The heights were (in inches) 24, 28, 25, 30, and 32. Do a one-way ANOVA test on the four groups. Are the heights of the bean plants different? Use the same method as shown in Example \(\PageIndex{4}\).
- Answer
-
- \(F = 0.9496\)
- \(p\text{-value} = 0.4402\)
From the sample data, the evidence is not sufficient to conclude that the mean heights of the bean plants are different.
Notation
The notation for the \(F\) distribution is \(F \sim F{df(\text{num}),df(\text{denom})}\)
where \(df(\text{num}) = df_{between} and df(\text{denom}) = df_{within}\)
The mean for the \(F\) distribution is \(\mu = \dfrac{df(\text{num})}{df(\text{denom}) - 1}\)
Review
Analysis of variance extends the comparison of two groups to several, each a level of a categorical variable (factor). Samples from each group are independent, and must be randomly selected from normal populations with equal variances. We test the null hypothesis of equal means of the response in every group versus the alternative hypothesis of one or more group means being different from the others. A one-way ANOVA hypothesis test determines if several population means are equal. The distribution for the test is the \(F\) distribution with two different degrees of freedom.
Assumptions:
- Each population from which a sample is taken is assumed to be normal.
- All samples are randomly selected and independent.
- The populations are assumed to have equal standard deviations (or variances).
The graph of the \(F\) distribution is always positive and skewed right, though the shape can be mounded or exponential depending on the combination of numerator and denominator degrees of freedom. The \(F\) statistic is the ratio of a measure of the variation in the group means to a similar measure of the variation within the groups. If the null hypothesis is correct, then the numerator should be small compared to the denominator. A small \(F\) statistic will result, and the area under the \(F\) curve to the right will be large, representing a large \(p\text{-value}\). When the null hypothesis of equal group means is incorrect, then the numerator should be large compared to the denominator, giving a large \(F\) statistic and a small area (small \(p\text{-value}\)) to the right of the statistic under the \(F\) curve.
When the data have unequal group sizes (unbalanced data), then techniques discussed earlier need to be used for hand calculations. In the case of balanced data (the groups are the same size) however, simplified calculations based on group means and variances may be used. In practice, of course, software is usually employed in the analysis. As in any analysis, graphs of various sorts should be used in conjunction with numerical techniques. Always look of your data!
Analysis of variance compares the means of a response variable for several groups. ANOVA compares the variation within each group to the variation of the mean of each group. The ratio of these two is the \(F\) statistic from an \(F\) distribution with (number of groups – 1) as the numerator degrees of freedom and (number of observations – number of groups) as the denominator degrees of freedom. These statistics are summarized in the ANOVA table.
Glossary
- Analysis of Variance
- also referred to as ANOVA, is a method of testing whether or not the means of three or more populations are equal. The method is applicable if:
- all populations of interest are normally distributed.
- the populations have equal standard deviations.
- samples (not necessarily of the same size) are randomly and independently selected from each population.
The test statistic for analysis of variance is the \(F\)-ratio.
- One-WayANOVA
- a method of testing whether or not the means of three or more populations are equal; the method is applicable if:
- all populations of interest are normally distributed.
- the populations have equal standard deviations.
- samples (not necessarily of the same size) are randomly and independently selected from each population.
The test statistic for analysis of variance is the \(F\)-ratio.
- Variance
- mean of the squared deviations from the mean; the square of the standard deviation. For a set of data, a deviation can be represented as \(x - \bar{x}\) where \(x\) is a value of the data and \(\bar{x}\) is the sample mean. The sample variance is equal to the sum of the squares of the deviations divided by the difference of the sample size and one.
Formula Review
\(SS_{between} = \sum \left[\dfrac{(s_{j})^{2}}{n_{j}}\right] - \dfrac{\left(\sum s_{j}\right)^{2}}{n}\)
\(SS_{\text{total}} = \sum x^{2} - \dfrac{\left(\sum x\right)^{2}}{n}\)
\(SS_{\text{within}} = SS_{\text{total}} - SS_{\text{between}}\)
\(df_{\text{between}} = df(\text{num}) = k - 1\)
\(df_{\text{within}} = df(\text{denom}) = n - k\)
\(MS_{\text{between}} = \dfrac{SS_{\text{between}}}{df_{\text{between}}}\)
\(MS_{\text{within}} = \dfrac{SS_{\text{within}}}{df_{\text{within}}}\)
\(F = \dfrac{MS_{\text{between}}}{MS_{\text{within}}}\)
\(F\) ratio when the groups are the same size: \(F = \dfrac{ns_{\bar{x}}^{2}}{s^{2}_{\text{pooled}}}\)
Mean of the \(F\) distribution: \(\mu = \dfrac{df(\text{num})}{df(\text{denom}) - 1}\)
where:
- \(k =\) the number of groups
- \(n_{j} =\) the size of the \(j^{th}\) group
- \(s_{j} =\) the sum of the values in the \(j^{th}\) group
- \(n =\) the total number of all values (observations) combined
- \(x =\) one value (one observation) from the data
- \(s_{\bar{x}}^{2} =\) the variance of the sample means
- \(s^{2}_{\text{pooled}} =\) the mean of the sample variances (pooled variance)
References
- Data from a fourth grade classroom in 1994 in a private K – 12 school in San Jose, CA.
- Hand, D.J., F. Daly, A.D. Lunn, K.J. McConway, and E. Ostrowski. A Handbook of Small Datasets: Data for Fruitfly Fecundity. London: Chapman & Hall, 1994.
- Hand, D.J., F. Daly, A.D. Lunn, K.J. McConway, and E. Ostrowski. A Handbook of Small Datasets.London: Chapman & Hall, 1994, pg. 50.
- Hand, D.J., F. Daly, A.D. Lunn, K.J. McConway, and E. Ostrowski. A Handbook of Small Datasets. London: Chapman & Hall, 1994, pg. 118.
- “MLB Standings – 2012.” Available online at http://espn.go.com/mlb/standings/_/year/2012.
- Mackowiak, P. A., Wasserman, S. S., and Levine, M. M. (1992), "A Critical Appraisal of 98.6 Degrees F, the Upper Limit of the Normal Body Temperature, and Other Legacies of Carl Reinhold August Wunderlich," Journal of the American Medical Association, 268, 1578-1580.
- Tomato Data, Marist College School of Science (unpublished student research)
Contributors and Attributions
Barbara Illowsky and Susan Dean (De Anza College) with many other contributing authors. Content produced by OpenStax College is licensed under a Creative Commons Attribution License 4.0 license. Download for free at http://cnx.org/contents/30189442-699...b91b9de@18.114.