
10.3: The Regression Equation and Prediction
- Page ID
- 10996

\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\( \newcommand{\dsum}{\displaystyle\sum\limits} \)
\( \newcommand{\dint}{\displaystyle\int\limits} \)
\( \newcommand{\dlim}{\displaystyle\lim\limits} \)
\( \newcommand{\id}{\mathrm{id}}\) \( \newcommand{\Span}{\mathrm{span}}\)
( \newcommand{\kernel}{\mathrm{null}\,}\) \( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\) \( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\) \( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\id}{\mathrm{id}}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\kernel}{\mathrm{null}\,}\)
\( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\)
\( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\)
\( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\) \( \newcommand{\AA}{\unicode[.8,0]{x212B}}\)
\( \newcommand{\vectorA}[1]{\vec{#1}} % arrow\)
\( \newcommand{\vectorAt}[1]{\vec{\text{#1}}} % arrow\)
\( \newcommand{\vectorB}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vectorC}[1]{\textbf{#1}} \)
\( \newcommand{\vectorD}[1]{\overrightarrow{#1}} \)
\( \newcommand{\vectorDt}[1]{\overrightarrow{\text{#1}}} \)
\( \newcommand{\vectE}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash{\mathbf {#1}}}} \)
\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\(\newcommand{\longvect}{\overrightarrow}\)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\(\newcommand{\avec}{\mathbf a}\) \(\newcommand{\bvec}{\mathbf b}\) \(\newcommand{\cvec}{\mathbf c}\) \(\newcommand{\dvec}{\mathbf d}\) \(\newcommand{\dtil}{\widetilde{\mathbf d}}\) \(\newcommand{\evec}{\mathbf e}\) \(\newcommand{\fvec}{\mathbf f}\) \(\newcommand{\nvec}{\mathbf n}\) \(\newcommand{\pvec}{\mathbf p}\) \(\newcommand{\qvec}{\mathbf q}\) \(\newcommand{\svec}{\mathbf s}\) \(\newcommand{\tvec}{\mathbf t}\) \(\newcommand{\uvec}{\mathbf u}\) \(\newcommand{\vvec}{\mathbf v}\) \(\newcommand{\wvec}{\mathbf w}\) \(\newcommand{\xvec}{\mathbf x}\) \(\newcommand{\yvec}{\mathbf y}\) \(\newcommand{\zvec}{\mathbf z}\) \(\newcommand{\rvec}{\mathbf r}\) \(\newcommand{\mvec}{\mathbf m}\) \(\newcommand{\zerovec}{\mathbf 0}\) \(\newcommand{\onevec}{\mathbf 1}\) \(\newcommand{\real}{\mathbb R}\) \(\newcommand{\twovec}[2]{\left[\begin{array}{r}#1 \\ #2 \end{array}\right]}\) \(\newcommand{\ctwovec}[2]{\left[\begin{array}{c}#1 \\ #2 \end{array}\right]}\) \(\newcommand{\threevec}[3]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \end{array}\right]}\) \(\newcommand{\cthreevec}[3]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \end{array}\right]}\) \(\newcommand{\fourvec}[4]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \\ #4 \end{array}\right]}\) \(\newcommand{\cfourvec}[4]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \\ #4 \end{array}\right]}\) \(\newcommand{\fivevec}[5]{\left[\begin{array}{r}#1 \\ #2 \\ #3 \\ #4 \\ #5 \\ \end{array}\right]}\) \(\newcommand{\cfivevec}[5]{\left[\begin{array}{c}#1 \\ #2 \\ #3 \\ #4 \\ #5 \\ \end{array}\right]}\) \(\newcommand{\mattwo}[4]{\left[\begin{array}{rr}#1 \amp #2 \\ #3 \amp #4 \\ \end{array}\right]}\) \(\newcommand{\laspan}[1]{\text{Span}\{#1\}}\) \(\newcommand{\bcal}{\cal B}\) \(\newcommand{\ccal}{\cal C}\) \(\newcommand{\scal}{\cal S}\) \(\newcommand{\wcal}{\cal W}\) \(\newcommand{\ecal}{\cal E}\) \(\newcommand{\coords}[2]{\left\{#1\right\}_{#2}}\) \(\newcommand{\gray}[1]{\color{gray}{#1}}\) \(\newcommand{\lgray}[1]{\color{lightgray}{#1}}\) \(\newcommand{\rank}{\operatorname{rank}}\) \(\newcommand{\row}{\text{Row}}\) \(\newcommand{\col}{\text{Col}}\) \(\renewcommand{\row}{\text{Row}}\) \(\newcommand{\nul}{\text{Nul}}\) \(\newcommand{\var}{\text{Var}}\) \(\newcommand{\corr}{\text{corr}}\) \(\newcommand{\len}[1]{\left|#1\right|}\) \(\newcommand{\bbar}{\overline{\bvec}}\) \(\newcommand{\bhat}{\widehat{\bvec}}\) \(\newcommand{\bperp}{\bvec^\perp}\) \(\newcommand{\xhat}{\widehat{\xvec}}\) \(\newcommand{\vhat}{\widehat{\vvec}}\) \(\newcommand{\uhat}{\widehat{\uvec}}\) \(\newcommand{\what}{\widehat{\wvec}}\) \(\newcommand{\Sighat}{\widehat{\Sigma}}\) \(\newcommand{\lt}{<}\) \(\newcommand{\gt}{>}\) \(\newcommand{\amp}{&}\) \(\definecolor{fillinmathshade}{gray}{0.9}\)Introduction
Data rarely fit a straight line exactly. Usually, you must be satisfied with rough predictions. Typically, you have a set of data whose scatter plot appears to "fit" a straight line. This is called a Line of Best Fit or Least-Squares Line. Before we delve deeper into these lines, let's do a review of Linear Equations first
Linear regression for two variables is based on a linear equation with one independent variable. The equation has the form:
\[y = a + b\text{x}\nonumber \]
where \(a\) and \(b\) are constant numbers. The variable \(x\) is the independent variable, and \(y\) is the dependent variable. Typically, you choose a value to substitute for the independent variable and then solve for the dependent variable.
The graph of a linear equation of the form \(y = a + b\text{x}\) is a straight line. Any line that is not vertical can be described by this equation.
Graph the equation \(y = -1 + 2\text{x}\).
For the linear equation \(y = a + b\text{x}\), \(b =\) slope and \(a = y\)-intercept. From algebra recall that the slope is a number that describes the steepness of a line, and the \(y\)-intercept is the \(y\) coordinate of the point \((0, a)\) where the line crosses the \(y\)-axis.

If you know a person's pinky (smallest) finger length, do you think you could predict that person's height? Collect data from your class (pinky finger length, in inches). The independent variable, \(x\), is pinky finger length and the dependent variable, \(y\), is height. For each set of data, plot the points on graph paper. Make your graph big enough and use a ruler. Then "by eye" draw a line that appears to "fit" the data. For your line, pick two convenient points and use them to find the slope of the line. Find the \(y\)-intercept of the line by extending your line so it crosses the \(y\)-axis. Using the slopes and the \(y\)-intercepts, write your equation of "best fit." Do you think everyone will have the same equation? Why or why not? According to your equation, what is the predicted height for a pinky length of 2.5 inches?
The Regression Equation
A random sample of 11 statistics students produced the following data, where \(x\) is the third exam score out of 80, and \(y\) is the final exam score out of 200.
In the previous section, we determined that our correlation coefficient was significant, so we should be able to predict the final exam score of a random student if you know their third exam score.
| \(x\) (third exam score) | \(y\) (final exam score) |
|---|---|
| 65 | 175 |
| 67 | 133 |
| 71 | 185 |
| 71 | 163 |
| 66 | 126 |
| 75 | 198 |
| 67 | 153 |
| 70 | 163 |
| 71 | 159 |
| 69 | 151 |
| 69 | 159 |
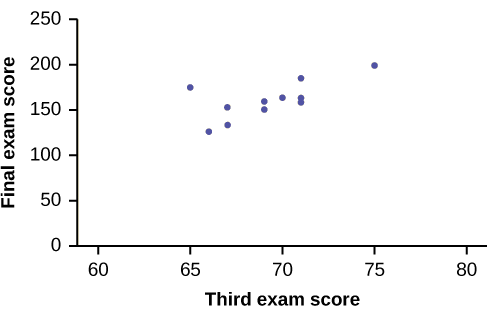
The third exam score, \(x\), is the independent variable and the final exam score, \(y\), is the dependent variable. We will plot a regression line that best "fits" the data. If each of you were to fit a line "by eye," you would draw different lines. We can use what is called a least-squares regression line to obtain the best fit line.
Consider the following diagram. Each point of data is of the the form (\(x, y\)) and each point of the line of best fit using least-squares linear regression has the form (\(x, \hat{y}\)).
The \(\hat{y}\) is read "\(y\) hat" and is the estimated value of \(y\). It is the value of \(y\) obtained using the regression line. It is not generally equal to \(y\) from data.
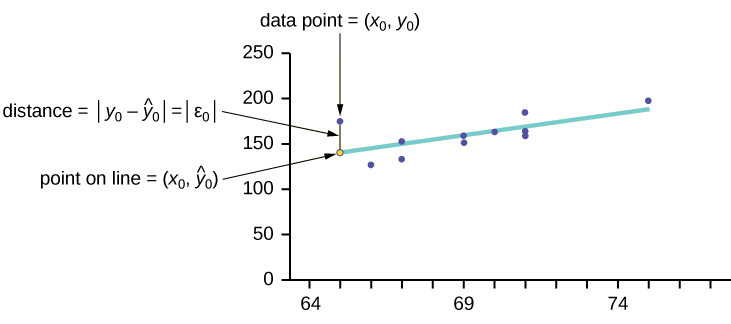
The term \(y_{0} – \hat{y}_{0} = \varepsilon_{0}\) is called the "error" or residual. It is not an error in the sense of a mistake. The absolute value of a residual measures the vertical distance between the actual value of \(y\) and the estimated value of \(y\). In other words, it measures the vertical distance between the actual data point and the predicted point on the line.
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for \(y\). If the observed data point lies below the line, the residual is negative, and the line overestimates that actual data value for \(y\).
In the diagram in Figure, \(y_{0} – \hat{y}_{0} = \varepsilon_{0}\) is the residual for the point shown. Here the point lies above the line and the residual is positive.
\(\varepsilon =\) the Greek letter epsilon
For each data point, you can calculate the residuals or errors, \(y_{i} - \hat{y}_{i} = \varepsilon_{i}\) for \(i = 1, 2, 3, ..., 11\).
Each \(|\varepsilon|\) is a vertical distance.
For the example about the third exam scores and the final exam scores for the 11 statistics students, there are 11 data points. Therefore, there are 11 \(\varepsilon\) values. If you square each \(\varepsilon\) and add, you get
\[(\varepsilon_{1})^{2} + (\varepsilon_{2})^{2} + \dotso + (\varepsilon_{11})^{2} = \sum^{11}_{i = 1} \varepsilon^{2} \label{SSE}\]
Equation\ref{SSE} is called the Sum of Squared Errors (SSE).
Using calculus, you can determine the values of \(a\) and \(b\) that make the SSE a minimum. When you make the SSE a minimum, you have determined the points that are on the line of best fit. It turns out that the line of best fit has the equation:
\[\hat{y} = a + bx\]
where
- \(a = \bar{y} - b\bar{x}\) and
- \(b = \dfrac{\sum(x - \bar{x})(y - \bar{y})}{\sum(x - \bar{x})^{2}}\).
The sample means of the \(x\) values and the \(x\) values are \(\bar{x}\) and \(\bar{y}\), respectively. The best fit line always passes through the point \((\bar{x}, \bar{y})\).
The slope \(b\) can be written as \(b = r\left(\dfrac{s_{y}}{s_{x}}\right)\) where \(s_{y} =\) the standard deviation of the \(y\) values and \(s_{x} =\) the standard deviation of the \(x\) values. \(r\) is the correlation coefficient.
Least Square Criteria for Best Fit
The process of fitting the best-fit line is called linear regression. The idea behind finding the best-fit line is based on the assumption that the data are scattered about a straight line. The criteria for the best fit line is that the sum of the squared errors (SSE) is minimized, that is, made as small as possible. Any other line you might choose would have a higher SSE than the best fit line. This best fit line is called the least-squares regression line .
Note
Computer spreadsheets, statistical software, and many calculators can quickly calculate the best-fit line and create the graphs. The calculations tend to be tedious if done by hand. Instructions to use the TI-83, TI-83+, and TI-84+ calculators to find the best-fit line and create a scatterplot are shown at the end of this section.
THIRD EXAM vs FINAL EXAM EXAMPLE:
The graph of the line of best fit for the third-exam/final-exam example is as follows:
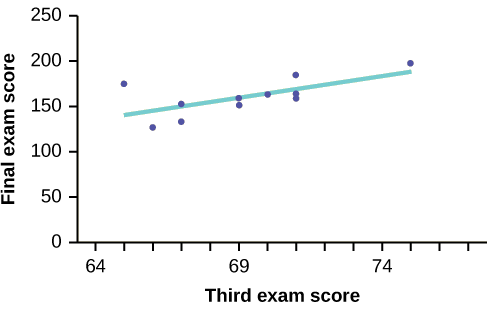
The least squares regression line (best-fit line) for the third-exam/final-exam example has the equation:
\[\hat{y} = -173.51 + 4.83x\]
REMINDER
Remember, it is always important to plot a scatter diagram first. If the scatter plot indicates that there is a linear relationship between the variables, then it is reasonable to use a best fit line to make predictions for \(y\) given \(x\) within the domain of \(x\)-values in the sample data, but not necessarily for x-values outside that domain. You could use the line to predict the final exam score for a student who earned a grade of 73 on the third exam. You should NOT use the line to predict the final exam score for a student who earned a grade of 50 on the third exam, because 50 is not within the domain of the \(x\)-values in the sample data, which are between 65 and 75.
Understanding Slope
The slope of the line, \(b\), describes how changes in the variables are related. It is important to interpret the slope of the line in the context of the situation represented by the data. You should be able to write a sentence interpreting the slope in plain English.
INTERPRETATION OF THE SLOPE: The slope of the best-fit line tells us how the dependent variable (\(y\)) changes for every one unit increase in the independent (\(x\)) variable, on average.
THIRD EXAM vs FINAL EXAM EXAMPLE
Slope: The slope of the line is \(b = 4.83\).
Interpretation: For a one-point increase in the score on the third exam, the final exam score increases by 4.83 points, on average.
USING THE TI-83, 83+, 84, 84+ CALCULATOR
Using the Linear Regression T Test: LinRegTTest
- In the STAT list editor, enter the \(X\) data in list L1 and the Y data in list L2, paired so that the corresponding (\(x,y\)) values are next to each other in the lists. (If a particular pair of values is repeated, enter it as many times as it appears in the data.)
- On the STAT TESTS menu, scroll down with the cursor to select the LinRegTTest. (Be careful to select LinRegTTest, as some calculators may also have a different item called LinRegTInt.)
- On the LinRegTTest input screen enter: Xlist: L1 ; Ylist: L2 ; Freq: 1
- On the next line, at the prompt \(\beta\) or \(\rho\), highlight "\(\neq 0\)" and press ENTER
- Leave the line for "RegEq:" blank
- Highlight Calculate and press ENTER.
The output screen contains a lot of information. For now we will focus on a few items from the output, and will return later to the other items.
The second line says \(y = a + bx\). Scroll down to find the values \(a = -173.513\), and \(b = 4.8273\); the equation of the best fit line is \(\hat{y} = -173.51 + 4.83x\)
The two items at the bottom are \(r_{2} = 0.43969\) and \(r = 0.663\). For now, just note where to find these values; we will discuss them in the next two sections.
Graphing the Scatterplot and Regression Line
- We are assuming your \(X\) data is already entered in list L1 and your \(Y\) data is in list L2
- Press 2nd STATPLOT ENTER to use Plot 1
- On the input screen for PLOT 1, highlight On, and press ENTER
- For TYPE: highlight the very first icon which is the scatterplot and press ENTER
- Indicate Xlist: L1 and Ylist: L2
- For Mark: it does not matter which symbol you highlight.
- Press the ZOOM key and then the number 9 (for menu item "ZoomStat") ; the calculator will fit the window to the data
- To graph the best-fit line, press the "\(Y =\)" key and type the equation \(-173.5 + 4.83X\) into equation Y1. (The \(X\) key is immediately left of the STAT key). Press ZOOM 9 again to graph it.
- Optional: If you want to change the viewing window, press the WINDOW key. Enter your desired window using Xmin, Xmax, Ymin, Ymax
Note
Another way to graph the line after you create a scatter plot is to use LinRegTTest.
- Make sure you have done the scatter plot. Check it on your screen.
- Go to LinRegTTest and enter the lists.
- At RegEq: press VARS and arrow over to Y-VARS. Press 1 for 1:Function. Press 1 for 1:Y1. Then arrow down to Calculate and do the calculation for the line of best fit.
- Press \(Y = (\text{you will see the regression equation})\).
- Press GRAPH. The line will be drawn."
THIRD EXAM vs FINAL EXAM EXAMPLE: Summary
- The line of best fit is: \(\hat{y} = -173.51 + 4.83x\)
- The correlation coefficient is \(r = 0.6631\)
- The coefficient of determination is \(r^{2} = 0.6631^{2} = 0.4397\)
- Interpretation of \(r^{2}\) in the context of this example:
- Approximately 44% of the variation (0.4397 is approximately 0.44) in the final-exam grades can be explained by the variation in the grades on the third exam, using the best-fit regression line.
- Therefore, approximately 56% of the variation (\(1 - 0.44 = 0.56\)) in the final exam grades can NOT be explained by the variation in the grades on the third exam, using the best-fit regression line. (This is seen as the scattering of the points about the line.)
Prediction
Suppose you want to estimate, or predict, the mean final exam score of statistics students who received 73 on the third exam. The exam scores (\(x\)-values) range from 65 to 75. Since 73 is between the \(x\)-values 65 and 75, substitute \(x = 73\) into the equation. Then:
\[\hat{y} = -173.51 + 4.83(73) = 179.08\nonumber \]
We predict that statistics students who earn a grade of 73 on the third exam will earn a grade of 179.08 on the final exam, on average.
Recall the third exam/final exam example.
- What would you predict the final exam score to be for a student who scored a 66 on the third exam?
- What would you predict the final exam score to be for a student who scored a 90 on the third exam?
Solutions
a. The \(x\) values in the data are between 65 and 75. Sixty-six is inside of the domain of the observed \(x\) values in the data (independent variable), so we can reliably predict the final exam score for this student.
\[\hat{y} = -173.51 + 4.83(66) = 145.27\nonumber \]
b. The \(x\) values in the data are between 65 and 75. Ninety is outside of the domain of the observed \(x\) values in the data (independent variable), so you cannot reliably predict the final exam score for this student. (Even though it is possible to enter 90 into the equation for \(x\) and calculate a corresponding \(y\) value, the \(y\) value that you get will not be reliable.)
To understand really how unreliable the prediction can be outside of the observed \(x\)-values observed in the data, make the substitution \(x = 90\) into the equation.
\[\hat{y} = -173.51 + 4.83(90) = 261.19\nonumber \]
The final-exam score is predicted to be 261.19. The largest the final-exam score can be is 200.
Note: The process of predicting inside of the observed \(x\) values observed in the data is called interpolation. The process of predicting outside of the observed \(x\)-values observed in the data is called extrapolation.
SCUBA divers have maximum dive times they cannot exceed when going to different depths. The data in Table show different depths with the maximum dive times in minutes. Use your calculator to find the least squares regression line and predict the maximum dive time for 110 feet. What about 75 feet?
| \(X\) (depth in feet) | \(Y\) (maximum dive time) |
|---|---|
| 50 | 80 |
| 60 | 55 |
| 70 | 45 |
| 80 | 35 |
| 90 | 25 |
| 100 | 22 |
- Answer
-
First, verify that the requested prediction value is the domain of the observed \(x\) values in the data. Remember that we can't make a prediction, even if there is a relationship, if we are outside the the domain of the observed \(x\) values in the data.
We want \(\hat{y}\) when \(x=110\). 110 is outside the domain of the observed \(x\) values in the data, so we should not use this data set to make that prediction.
We want \(\hat{y}\) when \(x=75\). 75 is inside the domain of the observed \(x\) values in the data, so we can make a prediction. Verify if there is a linear relationship.
LinRegTTest:
p-value = 0.0020 which is less than a significance level of 0.05, so we can reject the null hypothesis and determine that \(r\) is significant. This means we can find the regression line and use it to predict the maximum dive time for 75 feet.
Remember to assign the correct list for your x and y variables. While switching them does not affect the correlation coefficient's value, it will make a big difference in your slope and y-intercept.
\(y=a+bx\)
\(a=127.2380952 \approx 127.24\)
\(b=-1.114285714 \approx -1.11\)
Which decimal places your mean and intercept are rounded to depends on how accurate you want your results. Less rounding will mean more accuracy.
\(\hat{y} = 127.24 – 1.11x\)
\(\hat{y} = 127.24 – 1.11(75) = 43.99\)
At 75 feet, a diver could dive for about 44 minutes.
What happens if we want to make a prediction for a data value that is inside the domain of the observed \(x\) values in the data, but we determine that there is not linear relationship? In this case, the best prediction we can make is to report the mean of the dependent variable, \(y\).
\[\hat{y} = \bar{y}=\dfrac{\Sigma y}{n} \nonumber\]
An receptionist wondered if there was a relationship between the number of minutes a client arrived late and the amount of time they spent in their appointment. The client typically calls ahead to verify it is still fine to come in, but it does impact the rest of the schedule. If there is a relationship, then it might help them decide if it is still fine for the client to come in. They gathered the following data set:
| Minutes after scheduled arrival time | Minutes spent in appointment |
|---|---|
| 12 | 24 |
| 8 | 19 |
| 15 | 27 |
| 10 | 25 |
| 8 | 23 |
| 14 | 22 |
| 11 | 28 |
| 13 | 24 |
| 10 | 20 |
| 15 | 23 |
| 9 | 26 |
| 12 | 21 |
The client said they are going to be 10 minutes late. Can we find a line of best fit to make a prediction for the appointment time?
Solution
Since we are given the number of minutes the client is late, we know that is our independent variable, \(x\), making the appointment time the dependent variable, \(y\). We construct a scatter plot to determine if there is potential for a linear relationship.

Visually, it does not appear to be a strong correlation, but there is a weak positively linear pattern, so it is worth looking into.
The requested time of 10 minutes is in the domain of the observed \(x\) values in the data, so we can make a prediction.
Let's do our significance test to see if we can use our regression equation.
LinRegTTest:
p-value = 0.4435 which is greater than a significance level of 0.05, so we cannot reject the null hypothesis, which means that \(r\) is not significant.
We cannot find the regression line and use it to predict the appointment time for being 10 minutes late. The best we will be able to do is report a prediction of the mean appointment time:
\[\hat{y} = \bar{y} = 23.5 \nonumber\]
So, for any given value for the number of minutes late, within the domain of the observed values in the data, the best prediction we can make for appointment time is 23.5 minutes.
A very bored dorm resident advisor wondered if there was a relationship between the age of their dorm's residents and the amount of time they spent in the shower.
They gathered the following data set:
| Age | Minutes Spent in Shower |
|---|---|
| 27 | 14 |
| 20 | 9 |
| 24 | 12 |
| 26 | 10 |
| 23 | 14 |
| 19 | 8 |
| 25 | 11 |
| 22 | 13 |
| 21 | 10 |
| 28 | 12 |
| 24 | 9 |
Could they use this data to predict the amount of time a 22 year old will spend in the shower?
- Answer
-
Since we are given the age, we know that is our independent variable, \(x\), making the shower time the dependent variable, \(y\). We construct a scatter plot to determine if there is potential for a linear relationship.

Figure \(\PageIndex{8}\): Scatter Plot for Age vs. Time Spent in Shower. Visually, it does not appear to be a strong correlation, but there is a weak positively linear pattern, so it is worth looking into.
The requested age of 22 is in the domain of the observed \(x\) values in the data, so we can make a prediction.
Let's do our significance test to see if we can use our regression equation.
LinRegTTest:
p-value = 0.1081 which is greater than a significance level of 0.05, so we cannot reject the null hypothesis, which means that \(r\) is not significant.
We cannot find the regression line and use it to predict the shower time for at 22 year old. The best we will be able to do is report a prediction of the mean shower time:
\[\hat{y} = \bar{y} = 11.1 \nonumber\]
So, for any given value of age, within the domain of the observed values in the data, the best prediction we can make for shower time is 11.1 minutes.
Summary
The most basic type of association is a linear association. This type of relationship can be defined algebraically by the equations used, numerically with actual or predicted data values, or graphically from a plotted curve. (Lines are classified as straight curves.) Algebraically, a linear equation typically takes the form \(y = mx + b\), where \(m\) and \(b\) are constants, \(x\) is the independent variable, \(y\) is the dependent variable. In a statistical context, a linear equation is written in the form \(y = a + bx\), where \(a\) and \(b\) are the constants. This form is used to help readers distinguish the statistical context from the algebraic context. In the equation \(y = a + b\text{x}\), the constant b that multiplies the \(x\) variable (\(b\) is called a coefficient) is called the slope. The constant a is called the \(y\)-intercept.
The slope of a line is a value that describes the rate of change between the independent and dependent variables. The slope tells us how the dependent variable (\(y\)) changes for every one unit increase in the independent (\(x\)) variable, on average. The \(y\)-intercept is used to describe the dependent variable when the independent variable equals zero.
A regression line, or a line of best fit, can be drawn on a scatter plot and used to predict outcomes for the \(x\) and \(y\) variables in a given data set or sample data. There are several ways to find a regression line, but usually the least-squares regression line is used because it creates a uniform line. Residuals, also called “errors,” measure the distance from the actual value of \(y\) and the estimated value of \(y\). The Sum of Squared Errors, when set to its minimum, calculates the points on the line of best fit. Regression lines can be used to predict values within the given set of data, but should not be used to make predictions for values outside the set of data.
After determining the presence of a strong correlation coefficient and calculating the line of best fit, you can use the least squares regression line to make predictions about your data as long as it is the domain of the observed values in the data.
If your hypothesis test does not show a significant correlation (if \(r\) is not strong), then you cannot use the line of best fit to predict anything. Instead, the best predicted value for a specific \(x\) value is the mean of the \(y\) values of the original data set.
Glossary
Linear regression is a procedure for fitting a straight line of the form \(\hat{y} = a + bx\) to data. The conditions for regression are:
- Linear In the population, there is a linear relationship that models the average value of \(y\) for different values of \(x\).
- Independent The residuals are assumed to be independent.
- Normal The \(y\) values are distributed normally for any value of \(x\).
- Equal variance The standard deviation of the \(y\) values is equal for each \(x\) value.
- Random The data are produced from a well-designed random sample or randomized experiment.
The slope \(b\) and intercept \(a\) of the least-squares line estimate the slope \(\beta\) and intercept \(\alpha\) of the population (true) regression line. To estimate the population standard deviation of \(y\), \(\sigma\), use the standard deviation of the residuals, \(s\). \(s = \sqrt{\frac{SEE}{n-2}}\). The variable \(\rho\) (rho) is the population correlation coefficient. To test the null hypothesis \(H_{0}: \rho =\) hypothesized value, use a linear regression t-test. The most common null hypothesis is \(H_{0}: \rho = 0\) which indicates there is no linear relationship between \(x\) and \(y\) in the population. The TI-83, 83+, 84, 84+ calculator function LinRegTTest can perform this test (STATS TESTS LinRegTTest).
Formula Review
\(y = a + b\text{x}\) where a is the \(y\)-intercept and \(b\) is the slope. The variable \(x\) is the independent variable and \(y\) is the dependent variable.
Least Squares Line or Line of Best Fit:
\[\hat{y} = a + bx\]
where
\[a = y\text{-intercept}\]
\[b = \text{slope}\]
Standard deviation of the residuals:
\[s = \sqrt{\frac{SSE}{n-2}}\]
where
\[SSE = \text{sum of squared errors}\]
\[n = \text{the number of data points}\]
References
- Data from the Centers for Disease Control and Prevention.
- Data from the National Center for HIV, STD, and TB Prevention.
- Data from the United States Census Bureau. Available online at www.census.gov/compendia/stat...atalities.html
- Data from the National Center for Health Statistics.